Feuerfest

Just the private blog of a Linux sysadmin

yt-dlp error "No video formats found" and how I learned about DASH and that my yt-dlp filter could be improved

I participated in an only workshop at the weekend and the organisers kindly provided the recording as an unlisted YouTube video. As I wanted to watch the video again at a later time I used my MeTube installation to download the YouTube video. Or rather: Tried to.

As the download would fail. MeTube would say no available formats could be found. The video however played nicely on YouTube!?

The setup

I use a self-hosted web frontend for yt-dlp in Docker called MeTube, configured through the YTDL_OPTIONS environment variable. My config looked like this:

YTDL_OPTIONS={ "cookiefile":"/downloads/cookies/cookies.txt", "format-sort": "res:1080", "format": "best[language^=de]/best[language^=en]/b", "merge_output_format": "mp4" }

The idea behind this filter was:

  1. Limit video to 1080p in quality (not higher)
  2. Use the best available version with German audio
  3. Else use the best available version with English audio
  4. Use whatever is available as fallback

Step 1: Debugging

Naturally my first move was to check what kind of formats are offered for this video in order to verify the error message.

user@host:~$ yt-dlp -F "https://www.youtube.com/watch?v=VIDEO_ID"

For clarity I removed some lines and columns to make it more easier to read:

ID  EXT   RESOLUTION │ VCODEC          ACODEC      MORE INFO
─────────────────────────────────────────────────────────────────────
139 m4a   audio only │ audio only      mp4a.40.5   low, m4a_dash
140 m4a   audio only │ audio only      mp4a.40.2   medium, m4a_dash
251 webm  audio only │ audio only      opus        medium, webm_dash
134 mp4   640x360    │ avc1.4D401E     video only  360p, mp4_dash
136 mp4   1280x720   │ avc1.64001F     video only  720p, mp4_dash
137 mp4   1920x1080  │ avc1.640028     video only  1080p, mp4_dash
398 mp4   1280x720   │ av01.0.05M.08   video only  720p, mp4_dash
399 mp4   1920x1080  │ av01.0.08M.08   video only  1080p, mp4_dash

Notice something? Every single format is either audio only or video only. There is not one single format which contains both. Remember that for later.

Step 2: Why my filter found nothing

In yt-dlp's format selection best (or b) means: the best single file which contains video AND audio. And there are none. So all three alternatives of my filter (best[language^=de], best[language^=en] and b) ran into the void. Hence the error: "No video formats found!". The formats exist, my filter just didn't select any of them.

Nowadays YouTube serves high-quality video and audio as separate streams (DASH, see my separate article). yt-dlp downloads both and merges them with ffmpeg (provided it is installed and yt-dlp can find it) afterwards. For this you need to select video and audio separately and join them with a +:

bv* = best video (the * also allows formats which already have audio)
ba = best audio
bv*+ba = download both and merge them

Step 3: The corrected filter?

"format": "bv*+ba[language^=de]/bv*+ba[language^=en]/bv*+ba/b"

Read from left to right: Best video plus German audio. If there is no German audio then best video plus English audio. If that doesn't work either, best video plus whatever audio there is. And only if everything fails, the old b as a last resort.

I tested this on the command line first and it worked.

However.. It failed for another video. The video had English and German audio, according to the filter I should have gotten the video with the German audio track, but I didn't.

And here is where DASH becomes relevant: ba works for non-combined formats ONLY, meaning: ba only matches results with "audio only" under RESOLUTION (when using yt-dlp -F) Which is the case when DASH is used. On older videos however this might not be the case and you have only combined formats available. ba simply ignores these and hence my /b fallback matched and gave me the default audio track.

For combined formats we have to use best or b.

Step 4: The new filter 

Long story short, I ended up with the following filter which takes care of both, combined and non-combined, formats along with audio-only content:

'YTDL_OPTIONS={ "format-sort": "res:1080", "format": "bv*+ba[language^=de]/bv*+ba[language^=en]/b[language^=de]/b[language^=en]/bv*+ba/b/ba[language^=de]/ba[language^=en]/ba", "merge_output_format":"mp4" }'

  • format: alternatives separated by /, tried left to right, first match wins
    1. bv*+ba[language^=de]: best "video only" + best German "audio only"
    2. bv*+ba[language^=en]: best "video only" + best English "audio only"
    3. b[language^=de]: best combined format with German audio
    4. b[language^=en]: best combined format with English audio
    5. bv*+ba: best "video only" + best "audio only", any language
    6. b: best combined video+audio format
    7. ba[language^=de]: best German audio-only (for content without video)
    8. ba[language^=en]: best English audio-only (for content without video)
    9. ba: best audio-only, any language

This should be sufficient for the future (I hope! 😂) as I also took care to handle audio-only content.
Comments

What is DASH (Dynamic Adaptive Streaming over HTTP) and why did it broke my yt-dlp filter?

When you run yt-dlp -F on a YouTube video you will see lots of entries ending in mp4_dash, webm_dash or m4a_dash. I thought at first that this is a new format, so I started searching. As my current filter would complain: "No video formats found!"

The short version

DASH stands for Dynamic Adaptive Streaming over HTTP, also known as MPEG-DASH. It is an international standard (first described in ISO/IEC 23009-1) for streaming video and audio over plain HTTP. The same protocol your browser uses to load any webpage.

The core idea: Don't send one big file. Cut the media into many small segments, offer them in several qualities, and let the player decide which quality it wants to fetch next. And reading this, I finally understood a bit more how some things related to streaming work (yeah, all that audio/video stuff is not my bright side).

The problem DASH solves

Before adaptive streaming there were basically two options to watch a video on the web:

  1. Download the whole file (progressive download)
    • Simple, but you can't react if your connection gets slower. The video just stutters and buffers.
  2. Special streaming servers and protocols like RTMP (remember Flash?)
    • They worked, but needed dedicated server software (remember RealServer or RealPlayer?), were a pain with firewalls and didn't play well with caches and CDNs from what I read.

DASH takes a different approach: A video is just a bunch of static files on a normal web server. No special server logic required. Any HTTP server or CDN can deliver it. That's a big reason why it became so popular.

How it works

1. Encoding: many qualities, small segments

The provider encodes the video several times, in different resolutions and bitrates (144p, 360p, 720p, 1080p, ...). Each of these versions is called a Representation. Every representation is then cut into segments, usually a few seconds long.

Video and audio are separate representations. (Keep this in mind if you want to setup yt-dlp!) Audio can also exist in several bitrates, codecs and languages.

2. The XML-manifest tying everthing together

A small XML file, the Media Presentation Description (MPD), describes what is available. Which representations exist, which codecs, which bitrates and where to find the segments.

A heavily simplified, non-working example - as there are many attributes, etc. missing, is below:
Note: I use YouTube IDs here to make it easier to understand how yt-dlp, DASH/MPD and YouTube play together:

<MPD type="static" mediaPresentationDuration="PT10M">
  <Period>
    <AdaptationSet mimeType="video/mp4">
      <Representation id="137" codecs="avc1.640028" width="1920" height="1080" bandwidth="3500000"/>
      <Representation id="136" codecs="avc1.64001F" width="1280" height="720"  bandwidth="2000000"/>
      <Representation id="134" codecs="avc1.4D401E" width="640"  height="360"  bandwidth="700000"/>
    </AdaptationSet>
    <AdaptationSet mimeType="audio/mp4" lang="de">
      <Representation id="140" codecs="mp4a.40.2" bandwidth="129000"/>
    </AdaptationSet>
  </Period>
</MPD>

The AdaptationSet groups interchangeable versions of the same thing (e.g. "the video in different resolutions" or "the German audio track in different bitrates"). The player picks one representation out of each set.

Real world examples can be found here, but I can't say if they are up-to-date or working:

3. The player does the thinking

The player downloads the MPD and then:

  1. Starts with a low or medium quality, so playback begins quickly.
  2. Measures how fast the segments arrive (and how full its buffer is).
  3. Switches to a higher or lower representation for the next segment, depending on the result.

That is the "adaptive" in the name. It's also why a YouTube video gets blurry for a moment when your WLAN is acting up, instead of stopping to buffer. The server isn't even involved in this decision. It just hands out files.

This provided a nice "Ahhh!"-moment for me, as now I understood the technical details of how streaming services achieve this.

How it plays out is basically this:

Server (plain HTTP):        Player:
video_1080p/seg001.m4s ---> fast connection -> fetch 1080p
video_1080p/seg002.m4s ---> fetch segment 2
video_360p/seg003.m4s  ---> connection drops -> switch to 360p
video_720p/seg004.m4s  ---> recovered -> raise to 720p
audio_de/seg001.m4s    ---> audio is fetched independently

Why video and audio are separate

This is the part that matters for yt-dlp. Because video and audio are independent representations, a provider doesn't need to store every combination of resolution and language as an own file. Imagine a video with 8 resolutions, 3 codecs and 5 languages. Without separation that would be 120 files (8*3*5). With DASH it is 24 video representations (8*3) plus 5 audio ones. And the player combines them on the fly.

The downside for us as downloaders: There is often no single file containing both video and audio in high quality. That's why a plain best format selector in yt-dlp can come up empty on YouTube, as I happened to experience today. You have to select video and audio separately and merge them (which needs ffmpeg), but luckily yt-dlp does this for us too if ffmpeg (see: https://github.com/yt-dlp/yt-dlp#strongly-recommended) can be found in your systems environment variables (like PATH).

To download a video with that filter, use:

user@host:~$ yt-dlp -f "bv*+ba" "URL"

bv* is the best video, ba the best audio and the + tells yt-dlp to download both and merge them.

DASH in the yt-dlp format list

In the yt-dlp -F output you recognise DASH streams by the _dash suffix in the MORE INFO column:
Note: For clarity I removed several columns (like FPS, CH, FILESIZE, etc.) in this output.

user@host:~$ yt-dlp -F https://www.youtube.com/watch?v=ID
[youtube] Extracting URL: https://www.youtube.com/watch?v=ID
[youtube] ID: Downloading webpage
[youtube] ID: Downloading visionos player API JSON
[youtube] ID: Downloading m3u8 information
[info] Available formats for ID:
ID  EXT   RESOLUTION │ VCODEC        ACODED      MORE INFO
─────────────────────────────────────────────────────────────────────
137 mp4   1920x1080  │ avc1.640028   video only  1080p, mp4_dash
140 m4a   audio only │ audio only    mp4a.40.2   medium, m4a_dash
251 webm  audio only │ audio only    opus        medium, webm_dash

The container (mp4, webm, m4a) is independent of DASH. DASH only describes how the media is delivered, not what is inside. It is codec-agnostic: H.264, VP9, AV1, AAC, Opus, all of that works.

And now you know why your player never asks you which of the 20 formats it should play and why the video quality automatically fixes it itself after network/bandwidth issues. 😅

Comments

Booting an Ubuntu LTS cloud-init QEMU VM inside a Proxmox VM

I needed a quick throwaway Ubuntu VM for some testing, so I reached for the classic combo: an Ubuntu cloud image, a local cloud-init NoCloud datasource served over HTTP, and a bare qemu-system-x86_64 invocation. Nothing fancy, I've done this a dozen times before - just that the last time was ages ago..

My first attempt looked like this:

root@vm:~# qemu-system-x86_64 -net nic \
    -net user -machine accel=kvm:tcg -m 512 \
    -nographic -hda noble-server-cloudimg-amd64.img \
    -smbios type=1,serial=ds='nocloud;s=http://127.0.0.1:8000/'

And of course, it didn't just work. Last time I did was ages ago and directly on the hardware of my rootserver, not my local Proxmox server. As it turned out, I had two separate problems in this command, and to make things even more interesting: Everything is executed inside a Debian 13 VM, which itself lives on top of Proxmox. A VM inside a VM. So every weirdness I hit had to be checked twice. Once for "Is this a QEMU problem?" and once for "Is this a nested-virtualization problem?".

Preface

I created the directory /root/temp and but the files there according to the cloud-init QEMU tutorial. Then I started a webserver via the http.server Python module.

Have a look at https://docs.cloud-init.io/en/latest/tutorial/qemu.html#define-the-configuration-data-files regarding the files and the content.

Problem 1: Stuck at "Booting from Hard Disk..."

The VM wouldn't get past the SeaBIOS boot message "Booting from Hard Disk...". It became stuck there, forever. Additionally I saw no request to the local webserver on port 8000/tcp.

Turns out this is entirely expected, once you know why. Ubuntu's released Noble Numbat (LTS) cloud image is built for UEFI boot. SeaBIOS, the legacy BIOS QEMU uses by default, has no idea what to do with the GPT-partitioned disk and just... stops. No error, no hint, just sitting at "Booting from Hard Disk...".

The fix is to hand the VM the proper UEFI firmware via the Open Virtual Machine Firmware (OVMF) package instead of relying on SeaBIOS:

apt-get install ovmf

If you find older posts, they mention the /usr/share/OVMF/OVMF_VARS.id file, but on Debian 13 there's a small surprise waiting here too, the package no longer ships the plain OVMF_CODE.fd or OVMF_VARS.fd files I was used to. Instead you get the 4M variants:

root@vm:~# ls /usr/share/OVMF/OVMF_VARS_4M.*
/usr/share/OVMF/OVMF_VARS_4M.fd  /usr/share/OVMF/OVMF_VARS_4M.ms.fd  /usr/share/OVMF/OVMF_VARS_4M.snakeoil.fd

The .ms.fd variant ships with Microsoft's Secure Boot certificates pre-enrolled, and .snakeoil.fd is pre-signed with a test certificate for Secure Boot development. Neither is what I wanted, so plain OVMF_VARS_4M.fd it is, paired with the matching OVMF_CODE_4M.fd. CODE and VARS need to come from the same "generation" (2M vs. 4M), mixing them doesn't end well.

You also don't want to point QEMU directly at the VARS file in /usr/share/OVMF/, copy it locally first, since QEMU will write to it (that's where your EFI variables actually live):

root@vm:~# cp /usr/share/OVMF/OVMF_VARS_4M.fd .

Problem 2: Wrong IP for the webserver

While I was at it, I remembered that the datasource URL is used inside the guest and therefore refers to the guest itself, not my Proxmox VM serving the cloud-init files. With QEMU's user-mode networking -net user, the host is reachable from inside the guest at the fixed address 10.0.2.2. And since I'm serving the metadata over HTTP rather than a local path, nocloud-net is the correct datasource identifier, not nocloud.

Putting it together:

root@vm:~# qemu-system-x86_64 \
  -machine q35,accel=kvm:tcg \
  -m 512 \
  -nographic \
  -drive if=pflash,format=raw,readonly=on,file=/usr/share/OVMF/OVMF_CODE_4M.fd \
  -drive if=pflash,format=raw,file=./OVMF_VARS_4M.fd \
  -drive file=noble-server-cloudimg-amd64.img,if=virtio,format=qcow2 \
  -net nic -net user \
  -smbios type=1,serial=ds='nocloud-net;s=http://10.0.2.2:8000/'

That got me past the boot prompt. Progress.

Problem 3: It boots, but agonizingly slowly

The VM eventually made it into the kernel, but everything crawled. The console was full of entries like this:

[  116.771971] workqueue: drm_fb_helper_damage_work hogged CPU for >10000us 32 times, consider switching to WQ_UNBOUND
Starting systemd-udevd version 255.4-1ubuntu8.16
[  148.409180] workqueue: drm_fb_helper_damage_work hogged CPU for >10000us 64 times, consider switching to WQ_UNBOUND
[  226.621365] workqueue: drm_fb_helper_damage_work hogged CPU for >10000us 128 times, consider switching to WQ_UNBOUND

These particular messages are a symptom, not the disease. What's actually going on: accel=kvm:tcg tells QEMU "Use KVM if you can, otherwise silently fall back to TCG (software emulation)". If, for whatever reason, KVM isn't available inside the nested VM, QEMU just quietly emulates the entire CPU in software which is orders of magnitude slower and explains why a workqueue would get starved for 10ms stretches and longer.

Since this whole setup is a VM inside a VM, the first suspect is always nested virtualization. So, checks on the Proxmox-hosted Debian VM:

root@vm:~# ls -la /dev/kvm
ls: cannot access '/dev/kvm': No such file or directory
root@vm:~# lscpu | grep -i virtualization
Virtualization type:                     full

As the /dev/kvm device isn't present, we now have confirmed that QEMU falls back to software emulation for the CPU.

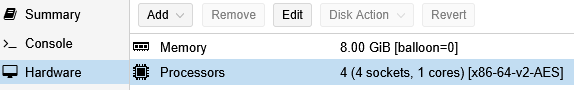
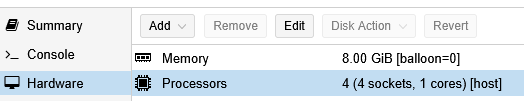
The solution? Changing the CPU for the VM in Proxmox from x86-64-v2-AES (or whatever is configured) to host. This enables the VM to directly use the CPU of my Proxmox host.

This can be done comfortably in the WebUI of Proxmox. Just power down the VM.

Before:

And after:

After a reboot we have a /dev/kvm device and full support for Intel VT-x virtualisation. This confirms Proxmox is passing VT-x through cleanly to the nested VM. So KVM should be usable in principle, meaning if the inner QEMU VM is still falling back to TCG, it's not because nested virt is broken at the Proxmox level.

root@vm:~# ls -la /dev/kvm
crw-rw---- 1 root kvm 10, 232 Jul 27 00:48 /dev/kvm
root@vm:~# lscpu | grep -i virtualization
Virtualization:                          VT-x
Virtualization type:                     full

To actually find out, instead of trusting the silent kvm:tcg fallback, it's better to force KVM explicitly and let it fail loudly if something's wrong:

root@vm:~# qemu-system-x86_64 \
  -machine q35,accel=kvm \
  -cpu host \
  -m 512 \
  -nographic \
  -drive if=pflash,format=raw,readonly=on,file=/usr/share/OVMF/OVMF_CODE_4M.fd \
  -drive if=pflash,format=raw,file=./OVMF_VARS_4M.fd \
  -drive file=noble-server-cloudimg-amd64.img,if=virtio,format=qcow2 \
  -net nic -net user \
  -smbios type=1,serial=ds='nocloud-net;s=http://10.0.2.2:8000/'

Removing the :tcg fallback means any KVM problem (permissions, missing nested virt on the Proxmox host CPU type, whatever) surfaces immediately as a hard error instead of a mysteriously slow VM. The parameter -cpu host on top makes sure the guest actually sees the hosts CPU features rather than a generic, lowest-common-denominator CPU model.

And the command worked, however, as we are still booting a VM inside a VM expect it to take some time. 😅

My learnings

For anyone hitting the same wall on their own Proxmox nested-VM setup, the checklist is:

  1. Is /dev/kvm present on the outer (Proxmox) VM at all?
  2. Is nested virtualization actually enabled on the Proxmox host itself?
    • # For Intel-CPUs - prints Y if enabled/available
      root@proxmox:~# cat /sys/module/kvm_intel/parameters/nested
      Y
      # For AMD-CPUs - prints Y if enabled/available
      root@proxmox:~# cat /sys/module/kvm_amd/parameters/nested
      Y
  3. Is the outer VM's CPU type set to host in the Proxmox config? So VMX/SVM flags get passed through
    • Check in the Hardware tab of the VM inside Proxmox's WebUI, or: 
    • Check with qm config VM-ID und verify the cpu line says host
      root@proxmox:~# qm config 100
      [...]
      cores: 1
      cpu: host
      [...]
  4. Does the inner QEMU call use accel=kvm (not kvm:tcg) plus -cpu host, so a broken KVM path fails loudly instead of silently degrading to software emulation?
  5. Is the /dev/kvm device present on the VM where you want to start the QEMU VM?
  6. Is CPU virtualization supported?

Nothing here is exotic once you know to look for it, but "silent TCG fallback" combined with "one VM inside another" is a pretty effective way to make a simple performance problem look mysterious for a while.

Comments

RedHat/Debian packages and Epoch numbers in packages

Another small important detail I learned today about epoch numbers in package names. Or rather: I was forced to understand what I already saw for years but never thought about.

RedHat's package manager yum (and by that extent also dnf and rpm) treat a non-specified epoch number as 0. This confused me today as a specified package couldn't be found. And an dnf info packagename didn't show the Epoch: field. Despite the package name clearly including an epoch version of 0.

Turns out this is document in RedHat Enterprise Linux 9: Advanced Topics - 6.3.1. The Epoch directive and Debian treats and Epoch number of 0 in the exact same way.

RedHat says:

The Epoch directive enables to define weighted dependencies based on version numbers.

If this directive is not listed in the RPM spec file, the Epoch directive is not set at all. This is contrary to common belief that not setting Epoch results in an Epoch of 0. However, the dnf utility treats an unset Epoch as the same as an Epoch of 0 for the purposes of depsolving.

However, listing Epoch in a spec file is usually omitted because in majority of cases introducing an Epoch value skews the expected RPM behavior when comparing versions of packages.

This effectivly means: If the epoch number is listed as None, it is 0. Just like in this example:

user@host:~$ rpm -q --qf "%{EPOCH}:%{NAME}-%{VERSION}-%{RELEASE}.%{ARCH}\n" bind-utils
(none):bind-utils-9.20.21-150700.3.18.1.x86_64

And Debian says pretty much the same in their manual regarding Control files and their fields: 5.6.12 version

epoch
This is a single (generally small) unsigned integer. It may be omitted, in which case zero is assumed.

Epochs can help when the upstream version numbering scheme changes, but they must be used with care. You should not change the epoch, even in experimental, without getting consensus on debian-devel first.

Interesting. I only had to use an Epoch number of 1 for a company internal Debian package once. As someone build a different package with the exact same name (despite the name having nothing to with what his because did) as this person just copy&pasted some build-scripts but apparently didn't change all important values. That was 10+ years ago.

Never stumbled about this particular case with how the 0 is treated.

You never stop learning.

Comments

MeTube: A selfhosted WebUI for yt-dlp

Most people should have heard of youtube-dl and the legal battles around it. As the content industry only saw it as a tool for piracy. And yes, while many may use it solely for that there is also the big group of people who want to download single TV news articles (videos) or documentaries produced by public-service broadcasting companies such as ARTE, ARD, ZDF - to name a few German ones. youtube-dl was sued into oblivion, but as it was OpenSource other forks were created with yt-dlp being the currently active one.

yt-dlp however is not just the only program offering this kind of functionality. As such there is the program MediathekView which gathers all senders program information and allows for the easy download of all content. Why MediathekView isn't sued? It only allows the download of content from the online Mediathek of public broadcasting companies, such as: ARD, ZDF, Arte, 3Sat, SWR, BR, MDR, NDR, WDR, HR, RBB, ORF and SRF. Which are all public broadcasting TV senders from Germany, Austria and Switzerland. Hence no problems with 3rd party rights do exist.

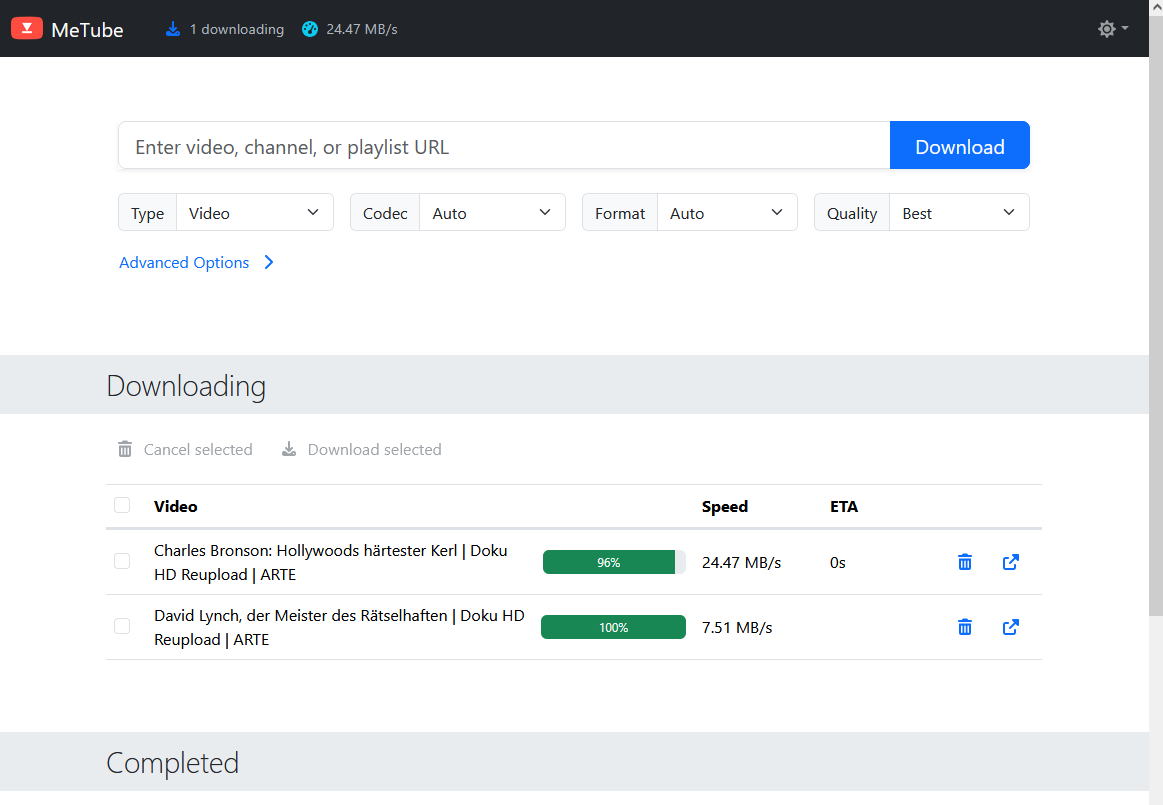
But... MediathekView is a local application and I like to have a simple web-frontend useable from any device. Introducing MeTube it's a web-frontend build around yt-dlp and provided as a Docker container. The WebUI itself is minimalistic but does its job.

Screenshot from the Metube WebUI(Click to enlarge)

In my environment MeTube is configured to save videos on a share on my NAS. Storing the videos in the correct folder automatically.

Mounting the CIFS-Share is done via the following line in /etc/fstab. As the directory is on a remote server it can become unavailable when the host is down. To circumvent this, we use the following mount parameters. Additionally we use a bind-mount propagation in the Dockerfile - actually the first time I ever did this. 😄

  • nofail: do not report errors for this device if it does not exist (see: man fstab)
  • _netdev: Using this option overrides this detection and specifies that the mount requires network (see: man systemd.mount)
  • x-systemd.automount: An automount unit will be created for the file system. (see: man systemd.automount and man systemd.mount)
  • x-systemd.mount-timeout=30: Configure how long systemd should wait for the mount command to finish before giving up on an entry from /etc/fstab (see: man systemd.mount)
root@portainer:~# cat /etc/fstab
# /etc/fstab: static file system information.
[...]
# Metube Mount
//ip.ip.ip.ip/video/yt-dlp /mnt/yt-dlp cifs rw,vers=3.0,credentials=/root/.fileserver_smbcredentials,dir_mode=0775,file_mode=0775,uid=1002,gid=1002,nofail,_netdev,x-systemd.automount,x-systemd.mount-timeout=30s

To activate the mount we use:

root@host:~# systemctl daemon-reload
root@host:~# mount -a
# This shows our mount as automount
root@host:~# systemctl list-dependencies remote-fs.target
remote-fs.target
○ └─mnt-yt\x2ddlp.automount

# If no automount is used, the entry is shown the following way:
root@host:~# systemctl list-dependencies remote-fs.target
remote-fs.target
● └─mnt-yt\x2ddlp.mount

If the mount isn't shown here there is no dependency to the remote-fs.target in systemd. Check if _netdev has been added. On most distributions _netdev isn't explicitly needed as network filesystems are discovered via the filesystem type - CIFS in our case.

Then we use that local mount for the /downloads folder of the Docker container. After the first start I learned I additionally need to explicitly store the TEMP_DIR and STATE_DIR on local volumes on the Docker container host itself. After that I fixed the healthcheck as it is hardcoded for HTTP.

services:
  metube:
    image: ghcr.io/alexta69/metube
    container_name: metube
    restart: unless-stopped
    ports:
      - "8081:8081"
    volumes:
      # On CIFS-Share, mounted via /etc/fstab
      # see https://docs.docker.com/engine/storage/bind-mounts/#configure-bind-propagation
      # on how bind propagation works
      - /mnt/yt-dlp:/downloads:slave
      # HTTPS
      - /opt/docker/certs/portainer.lan.crt:/ssl/crt.pem
      - /opt/docker/certs/portainer.lan.key:/ssl/key.pem
      # Local volumes to make CIFS-Share work
      - /opt/docker/metube/temp:/temporary
      - /opt/docker/metube/state:/state
    environment:
      - PUID=1002
      - PGID=1002
      # HTTPS
      - HTTPS=true
      - CERTFILE=/ssl/crt.pem
      - KEYFILE=/ssl/key.pem
      # Needed as our /downloads folder is located on a CIFS-Share
      - TEMP_DIR=/temporary
      - STATE_DIR=/state
      # Downloaded files are deleted on the server, when they are trashed from the "Completed" section of the UI
      #  - Will delete files from /download! This is not to clear some kind of cache
      #- DELETE_FILE_ON_TRASHCAN=true
      #
      # yt-dlp options
      # Prefer 1080p & audio in german language, if no german is available use english, else use default
      # Note 1: There are combined formats (audio+video in one file) and non-combined (listed as: "audio only" or "video only")
      # Note 2: ba[language^=de] is for "audio only" file, likewise b[language^=de] is for combined files only
      #   ^=de means we also take de-DE or de-AT, similiar for ^=en meaning en-UK, en-US, etc.
      # Note 3: To make our filter work with both, we have to use /b as fallback and /ba for audio-only content without video
      # Note 4: yt-dlp can't reliably identify the automatically generated audiotracks as these are not clearly listed as such in the metadata
      # Note 5: format-sort res:1080 means: Prefer 1080p, if not available download the next best smaller format. If no smaller format is available, download the next (smallest) higher format
      #
      # format: alternatives separated by /, tried left to right, first match wins
      #   bv*+ba[language^=de]: best video + best German audio
      #   bv*+ba[language^=en]: best video + best English audio
      #   b[language^=de]: best combined format with German audio
      #   b[language^=en]: best combined format with English audio
      #   bv*+ba: best video + best audio, any language
      #   b: best combined video+audio format
      #   ba[language^=de]: best German audio-only (for content without video)
      #   ba[language^=en]: best English audio-only (for content without video)
      #   ba: best audio-only, any language
      - 'YTDL_OPTIONS={ "format-sort": "res:1080", "format": "bv*+ba[language^=de]/bv*+ba[language^=en]/b[language^=de]/b[language^=en]/bv*+ba/b/ba[language^=de]/ba[language^=en]/ba", "merge_output_format":"mp4" }'
    # Internal container healthcheck is hardcoded for HTTP
    healthcheck:
        test: ["CMD-SHELL", "curl -fsS --insecure -m 2 https://localhost:8081/ || exit 1"]
        interval: 60s
        timeout: 10s
        retries: 3
        start_period: 10s

The only feature I currently miss is that I can't select the audio track which I do want to download along with the video. However having such options would only solve one part of the problem. As the other part would be that each site would need to clearly state which audio track contains which language. And that isn't even reliably done on YouTube.

Hence I help myself with passing some options to yt-dlp via YTDL_OPTIONS. My config 'YTDL_OPTIONS={ "format-sort": "res:1080", "format": "best[language^=de]/best[language^=en]/b", "merge_output_format": "mp4" }' means: Sort the videos based on the resolution, set 1080p as the highest (best). Videos in higher resolution won't be considered for download. Based on that we download the best video/audio available in German and if nothing is available in German we use English. If that isn't available too, we just use the default.

As stated in the comments of the Dockerfile the problem is that not every language has an audio only track. Only on those a bestaudio filter like ba[language^=en] would work. I encountered too many videos where the language was part of the video track, therefore I switched to just use best[language^=...]. This works more reliable from my experience. And yes, these settings overwrite everything you select in the web-frontend.

Nonetheless for the edge cases being able to define settings for a single download would be nice.

Turns out I got things wrong, October 2026 correction:

The filter I used didn't exactly do what I thought it did and happened to have problems with DASH.

This is my old filter I describe in this article:
'YTDL_OPTIONS={ "format-sort": "res:1080", "format": "best[language^=de]/best[language^=en]/b", "merge_output_format": "mp4" }'

Turns out best and b or for single files combining audio AND video. However, with standards like DASH these are separate files and hence MeTube/yt-dlp won't find anything to download.

Additionally it didn't limit downloads to a maximum quality of 1080p, instead it preferred it. If no 1080p format is available, it takes the best quality below 1080p (for example: 720p) and if no quality equal to or below 1080p is available it will take the next (smallest) format above the specified limit (like: 2k if only 2k and 4k are available).

However, I decided this is fine for me, as this is generally also what I want and it makes the whole filter a bit more robust.

So my new filter is:

'YTDL_OPTIONS={ "format-sort": "res:1080", "format": "bv*+ba[language^=de]/bv*+ba[language^=en]/b[language^=de]/b[language^=en]/bv*+ba/b/ba[language^=de]/ba[language^=en]/ba", "merge_output_format":"mp4" }'

It works the following (also already included in the Docker compose file above):

  • format: alternatives separated by /, tried left to right, first match wins
    1. bv*+ba[language^=de]: best video + best German audio
    2. bv*+ba[language^=en]: best video + best English audio
    3. b[language^=de]: best combined format with German audio
    4. b[language^=en]: best combined format with English audio
    5. bv*+ba: best video + best audio, any language
    6. b: best combined video+audio format
    7. ba[language^=de]: best German audio-only (for content without video)
    8. ba[language^=en]: best English audio-only (for content without video)
    9. ba: best audio-only, any language

Last tips

If you encounter any problem when downloading a video with yt-dlp make sure you have a JavaScript runtime installed (MeTube uses deno). You either need to specify the path to it in the config file or on the command line via: yt-dlp --js-runtimes deno:/path/to/deno -F URL as only then a -F will show you all available formats. Else some can be missing.

Secondly, use -s to simulate a run when testing your config. Like for my config above: yt-dlp --js-runtimes deno:/path/to/deno -s -S res:1080 -f "best[language^=de]/best[language^=en]/b" URL

Also pay attention to the log line that stated which video and audio track are being downloaded: [info] YouTube-VideoID: Downloading 1 format(s): 96-5. This number corresponds directly to the values you can retrieve with -F. Generally when your filter isn't working it mostly downloads the default video and audio track.

Generally I can recommend reading the yt-dlp readme on Format Selection.

Comments

Using rgxg (ReGular eXpression Generator) to generate a RegEx that matches all IPv4 & IPv6 addresses

In "Little Helper Scripts - Part 3: My Homelab CA Management Scripts", I mention that the regular expressions I use for identifying IPv4 and IPv6 addresses are rather basic. In particular, the IPv6 RegEx simply assumes that anything containing a colon is an IPv6 address.

When I jokingly asked on Mastodon if anyone had a better RegEx, I mentioned my script enhancements. My former colleague Klaus Umbach recommended rgxg (ReGular eXpression Generator) to me. It sounded like it would solve my problem exactly.

Installing rgxg

The installation on Debian is pretty easy as there is a package available.

root@host:~# apt-get install rgxg
Reading package lists... Done
Building dependency tree... Done
Reading state information... Done
The following additional packages will be installed:
  librgxg0
The following NEW packages will be installed:
  librgxg0 rgxg
0 upgraded, 2 newly installed, 0 to remove and 0 not upgraded.
Need to get 24.4 kB of archives.
After this operation, 81.9 kB of additional disk space will be used.
Do you want to continue? [Y/n]
Get:1 http://debian.tu-bs.de/debian bookworm/main amd64 librgxg0 amd64 0.1.2-5 [15.3 kB]
Get:2 http://debian.tu-bs.de/debian bookworm/main amd64 rgxg amd64 0.1.2-5 [9,096 B]
Fetched 24.4 kB in 0s (200 kB/s)
Selecting previously unselected package librgxg0:amd64.
(Reading database ... 40580 files and directories currently installed.)
Preparing to unpack .../librgxg0_0.1.2-5_amd64.deb ...
Unpacking librgxg0:amd64 (0.1.2-5) ...
Selecting previously unselected package rgxg.
Preparing to unpack .../rgxg_0.1.2-5_amd64.deb ...
Unpacking rgxg (0.1.2-5) ...
Setting up librgxg0:amd64 (0.1.2-5) ...
Setting up rgxg (0.1.2-5) ...
Processing triggers for man-db (2.11.2-2) ...
Processing triggers for libc-bin (2.36-9+deb12u10) ...
root@host:~#

Generating a RegEx for IPv6 and IPv4

Klaus already delivered the example for the complete IPv6 address space. For IPv4 it is equally easy:

# RegEx for the complete IPv6 address space
user@host:~$ rgxg cidr ::0/0
((:(:[0-9A-Fa-f]{1,4}){1,7}|::|[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4}){1,6}|::|:[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4}){1,5}|::|:[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4}){1,4}|::|:[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4}){1,3}|::|:[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4}){1,2}|::|:[0-9A-Fa-f]{1,4}(::[0-9A-Fa-f]{1,4}|::|:[0-9A-Fa-f]{1,4}(::|:[0-9A-Fa-f]{1,4}))))))))|(:(:[0-9A-Fa-f]{1,4}){0,5}|[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4}){0,4}|:[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4}){0,3}|:[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4}){0,2}|:[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4})?|:[0-9A-Fa-f]{1,4}(:|:[0-9A-Fa-f]{1,4})))))):(25[0-5]|2[0-4][0-9]|1[0-9]{2}|[1-9]?[0-9])(\.(25[0-5]|2[0-4][0-9]|1[0-9]{2}|[1-9]?[0-9])){3})

# RegEx for the complete IPv4 address space
user@host:~$ rgxg cidr 0.0.0.0/0
(25[0-5]|2[0-4][0-9]|1[0-9]{2}|[1-9]?[0-9])(\.(25[0-5]|2[0-4][0-9]|1[0-9]{2}|[1-9]?[0-9])){3}

Modifying hostcert.sh

All that is left to is define definite start and endpoints for the RegEx (^ and $) and test it.

user@host:~/git/github/chrlau/scripts/ca$ git diff
diff --git a/ca/hostcert.sh b/ca/hostcert.sh
index f743881..26ec0b0 100755
--- a/ca/hostcert.sh
+++ b/ca/hostcert.sh
@@ -42,16 +42,18 @@ else
        CN="$1.lan"
 fi

-# Check if Altname is an IPv4 or IPv6 (yeah.. very basic check..)
-#  so we can set the proper x509v3 extension
+# Check if Altname is an IPv4 or IPv6 - so we can set the proper x509v3 extension
+# Note: Everything which doesn't match the IPv4 or IPv6 RegEx is treated as DNS altname!
 for ALTNAME in $*; do
-  if [[ $ALTNAME =~ ^[0-9]+\.[0-9]+\.[0-9]+\.[0-9]+$ || $ALTNAME =~ \.*:\.* ]]; then
+  if [[ $ALTNAME =~ ^(25[0-5]|2[0-4][0-9]|1[0-9]{2}|[1-9]?[0-9])(\.(25[0-5]|2[0-4][0-9]|1[0-9]{2}|[1-9]?[0-9])){3}$ || $ALTNAME =~ ^((:(:[0-9A-Fa-f]{1,4}){1,7}|::|[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4}){1,6}|::|:[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4}){1,5}|::|:[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4}){1,4}|::|:[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4}){1,3}|::|:[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4}){1,2}|::|:[0-9A-Fa-f]{1,4}(::[0-9A-Fa-f]{1,4}|::|:[0-9A-Fa-f]{1,4}(::|:[0-9A-Fa-f]{1,4}))))))))|(:(:[0-9A-Fa-f]{1,4}){0,5}|[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4}){0,4}|:[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4}){0,3}|:[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4}){0,2}|:[0-9A-Fa-f]{1,4}(:(:[0-9A-Fa-f]{1,4})?|:[0-9A-Fa-f]{1,4}(:|:[0-9A-Fa-f]{1,4})))))):(25[0-5]|2[0-4][0-9]|1[0-9]{2}|[1-9]?[0-9])(\.(25[0-5]|2[0-4][0-9]|1[0-9]{2}|[1-9]?[0-9])){3})$ ]]; then
+  #if [[ $ALTNAME =~ ^[0-9]+\.[0-9]+\.[0-9]+\.[0-9]+$ || $ALTNAME =~ \.*:\.* ]]; then
     IP_ALTNAMES+=("$ALTNAME")
   else
     DNS_ALTNAMES+=("$ALTNAME")
   fi
 done

+# TODO: Add DNS check against all DNS Altnames (CN is always part of DNS Altnames)
 echo "CN: $CN"
 echo "DNS ANs: ${DNS_ALTNAMES[@]}"
 echo "IP ANs: ${IP_ALTNAMES[@]}"

And it seems to work fine. Notably all altnames who don't match any of the RegExes are treated as DNS-Altname which can cause trouble hence I think about adding a check to resolve all provided DNS names prior the certificate creation.

root@host:~/ca# ./hostcert.sh service.lan 1.2.3.4 fe80::1234 service-test.lan 2abt::0000 999.5.4.2 2a00:1:2:3:4:5::ffff
CN: service.lan
DNS ANs: service.lan service-test.lan 2abt::0000 999.5.4.2
IP ANs: 1.2.3.4 fe80::1234 2a00:1:2:3:4:5::ffff
Enter to confirm.
^C
root@host:~/ca#
Comments