Feuerfest

Just the private blog of a Linux sysadmin

MeTube: A selfhosted WebUI for yt-dlp

Most people should have heard of youtube-dl and the legal battles around it. As the content industry only saw it as a tool for piracy. And yes, while many may use it solely for that there is also the big group of people who want to download single TV news articles (videos) or documentaries produced by public-service broadcasting companies such as ARTE, ARD, ZDF - to name a few German ones. youtube-dl was sued into oblivion, but as it was OpenSource other forks were created with yt-dlp being the currently active one.

yt-dlp however is not just the only program offering this kind of functionality. As such there is the program MediathekView which gathers all senders program information and allows for the easy download of all content. Why MediathekView isn't sued? It only allows the download of content from the online Mediathek of public broadcasting companies, such as: ARD, ZDF, Arte, 3Sat, SWR, BR, MDR, NDR, WDR, HR, RBB, ORF and SRF. Which are all public broadcasting TV senders from Germany, Austria and Switzerland. Hence no problems with 3rd party rights do exist.

But... MediathekView is a local application and I like to have a simple web-frontend useable from any device. Introducing MeTube it's a web-frontend build around yt-dlp and provided as a Docker container. The WebUI itself is minimalistic but does its job.
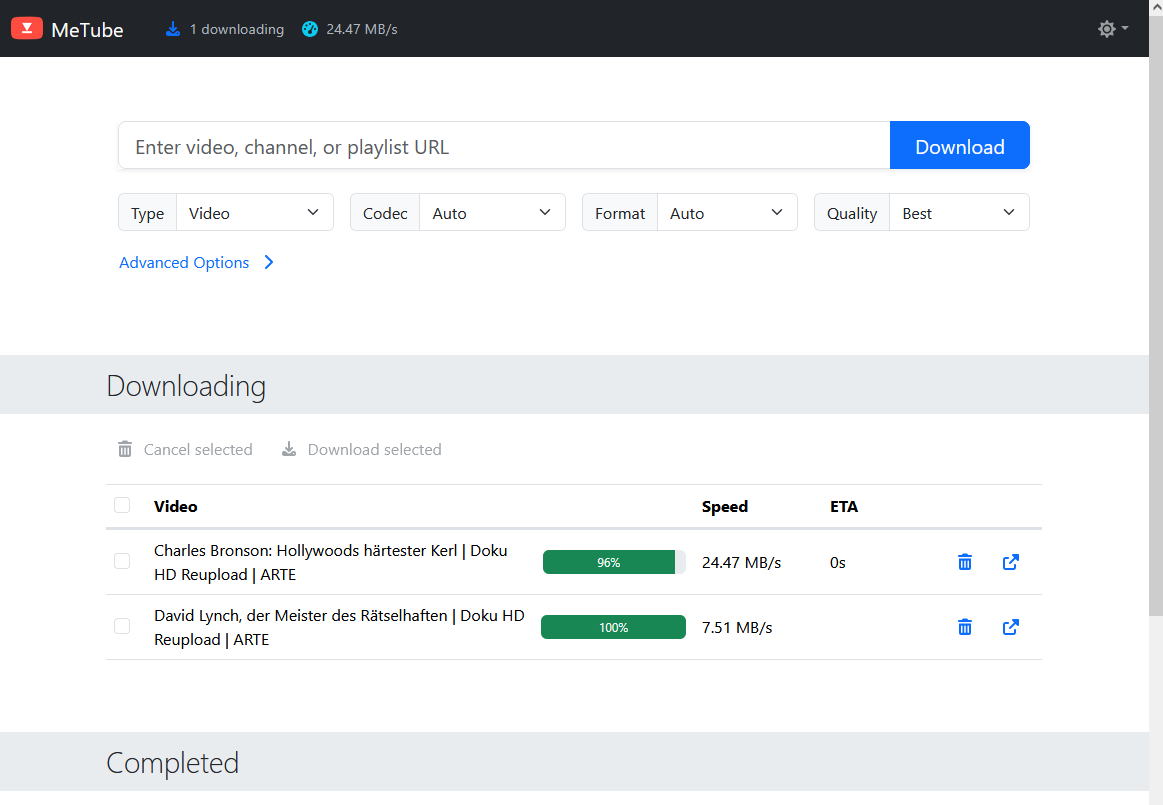
Screenshot from the Metube WebUI(Click to enlarge)

In my environment MeTube is configured to save videos on a share on my NAS. Storing the videos in the correct folder automatically.

Mounting the CIFS-Share is done via the following line in /etc/fstab. As the directory is on a remote server it can become unavailable when the host is down. To circumvent this, we use the following mount parameters. Additionally we use a bind-mount propagation in the Dockerfile - actually the first time I ever did this. 😄

  • nofail: do not report errors for this device if it does not exist (see: man fstab)
  • _netdev: Using this option overrides this detection and specifies that the mount requires network (see: man systemd.mount)
  • x-systemd.automount: An automount unit will be created for the file system. (see: man systemd.automount and man systemd.mount)
  • x-systemd.mount-timeout=30: Configure how long systemd should wait for the mount command to finish before giving up on an entry from /etc/fstab (see: man systemd.mount)
root@portainer:~# cat /etc/fstab
# /etc/fstab: static file system information.
[...]
# Metube Mount
//ip.ip.ip.ip/video/yt-dlp /mnt/yt-dlp cifs rw,vers=3.0,credentials=/root/.fileserver_smbcredentials,dir_mode=0775,file_mode=0775,uid=1002,gid=1002,nofail,_netdev,x-systemd.automount,x-systemd.mount-timeout=30s

To activate the mount we use:

root@host:~# systemctl daemon-reload
root@host:~# mount -a
# This shows our mount as automount
root@host:~# systemctl list-dependencies remote-fs.target
remote-fs.target
○ └─mnt-yt\x2ddlp.automount

# If no automount is used, the entry is shown the following way:
root@host:~# systemctl list-dependencies remote-fs.target
remote-fs.target
● └─mnt-yt\x2ddlp.mount

If the mount isn't shown here there is no dependency to the remote-fs.target in systemd. Check if _netdev has been added. On most distributions _netdev isn't explicitly needed as network filesystems are discovered via the filesystem type - CIFS in our case.

Then we use that local mount for the /downloads folder of the Docker container. After the first start I learned I additionally need to explicitly store the TEMP_DIR and STATE_DIR on local volumes on the Docker container host itself. After that I fixed the healthcheck as it is hardcoded for HTTP.

services:
  metube:
    image: ghcr.io/alexta69/metube
    container_name: metube
    restart: unless-stopped
    ports:
      - "8081:8081"
    volumes:
      # On CIFS-Share, mounted via /etc/fstab
      # see https://docs.docker.com/engine/storage/bind-mounts/#configure-bind-propagation
      # on how bind propagation works
      - /mnt/yt-dlp:/downloads:slave
      # HTTPS
      - /opt/docker/certs/portainer.lan.crt:/ssl/crt.pem
      - /opt/docker/certs/portainer.lan.key:/ssl/key.pem
      # Local volumes to make CIFS-Share work
      - /opt/docker/metube/temp:/temporary
      - /opt/docker/metube/state:/state
    environment:
      - PUID=1002
      - PGID=1002
      # HTTPS
      - HTTPS=true
      - CERTFILE=/ssl/crt.pem
      - KEYFILE=/ssl/key.pem
      # Needed as our /downloads folder is located on a CIFS-Share
      - TEMP_DIR=/temporary
      - STATE_DIR=/state
      # Downloaded files are deleted on the server, when they are trashed from the "Completed" section of the UI
      #  - Will delete files from /download! This is not to clear some kind of cache
      #- DELETE_FILE_ON_TRASHCAN=true
      #
      # yt-dlp options
      # Download best video (not higher than 1080p) & audio in german language, if no german is available use english, else use default
      # Note 1: Not every language has a separate "audio only" track, this is why we use best[language...], as ba[language=...] only matches "audio only" tracks
      # Note 2: yt-dlp can't reliably identify the automatically generated audiotracks as these are not clearly listed as such in the metadata
      #   format-sort res:1080 means: Not higher than 1080p
      #   ^=de means we also take de-DE or de-AT, similiar for ^=en meaning en-UK, en-US, etc.
      - 'YTDL_OPTIONS={ "format-sort": "res:1080", "format": "best[language^=de]/best[language^=en]/b", "merge_output_format": "mp4" }'
    # Internal container healthcheck is hardcoded for HTTP
    healthcheck:
        test: ["CMD-SHELL", "curl -fsS --insecure -m 2 https://localhost:8081/ || exit 1"]
        interval: 60s
        timeout: 10s
        retries: 3
        start_period: 10s

The only feature I currently miss is that I can't select the audio track which I do want to download along with the video. However having such options would only solve one part of the problem. As the other part would be that each site would need to clearly state which audio track contains which language. And that isn't even reliably done on YouTube.

Hence I help myself with passing some options to yt-dlp via YTDL_OPTIONS. My config 'YTDL_OPTIONS={ "format-sort": "res:1080", "format": "best[language^=de]/best[language^=en]/b", "merge_output_format": "mp4" }' means: Sort the videos based on the resolution, set 1080p as the highest (best). Videos in higher resolution won't be considered for download. Based on that we download the best video/audio available in German and if nothing is available in German we use English. If that isn't available too, we just use the default.

As stated in the comments of the Dockerfile the problem is that not every language has an audio only track. Only on those a bestaudio filter like ba[language^=en] would work. I encountered too many videos where the language was part of the video track, therefore I switched to just use best[language^=...]. This works more reliable from my experience. And yes, these settings overwrite everything you select in the web-frontend.

Nonetheless for the edge cases being able to define settings for a single download would be nice.

Last tips

If you encounter any problem when downloading a video with yt-dlp make sure you have a JavaScript runtime installed (MeTube uses deno). You either need to specify the path to it in the config file or on the command line via: yt-dlp --js-runtimes deno:/path/to/deno -F URL as only then a -F will show you all available formats. Else some can be missing.

Secondly, use -s to simulate a run when testing your config. Like for my config above: yt-dlp --js-runtimes deno:/path/to/deno -s -S res:1080 -f "best[language^=de]/best[language^=en]/b" URL

Also pay attention to the log line that stated which video and audio track are being downloaded: [info] YouTube-VideoID: Downloading 1 format(s): 96-5. This number corresponds directly to the values you can retrieve with -F. Generally when your filter isn't working it mostly downloads the default video and audio track.

Generally I can recommend reading the yt-dlp readme on Format Selection.
Comments

A better approach to enable line-numbers in Bludit code-blocks

In my posts Things to do when updating Bludit and Bludit and syntax highlighting I detailed how to get line-numbers displayed. It always annoyed me that it involved direct code-changes in the codesample-Plugin's code from TinyMCE.

Today I updated to Bludit 3.18.4, did the manual changes, but alas no line-numbers. Nothing worked, no errors displayed. Strange.

I took the Problem to ClaudeAI and it recommended a whole different approach which I like even better. By creating a js/custom-linenumbers.js file in the admin-Theme and integrate this via a <script>-Element. The js/custom-linenumbers.js will take care of changing the <pre class="language- tags by adding line-numbers. This all happens in the background and is saved, when the article is saved. Nice!

This effectively means I don't have to do manually change code anymore. Just add a line into the update the bl-kernel/admin/themes/booty/index.php file and maybe updating the prism.js/prism.css from time to time while ensuring that the line-numbers plugin is included. Sweet!

How to integrate the custom-linenumbers.js file into the Bludit admin theme

First we create the following file as bl-kernel/admin/themes/booty/js/custom-linenumbers.js:

console.log('Loaded: custom-linenumbers.js');
// Adds the line-numbers plugin from PRISM to all <pre class="language- tags
document.addEventListener('DOMContentLoaded', function() {
    if (typeof tinymce !== 'undefined') {
        tinymce.on('AddEditor', function(e) {
            var editor = e.editor;
            editor.on('GetContent', function(evt) {
                if (evt.content && evt.content.indexOf('language-') !== -1) {
                    // Create temporary DOM-Element
                    var tempDiv = document.createElement('div');
                    tempDiv.innerHTML = evt.content;

                    // Check <pre> Tags
                    var codeBlocks = tempDiv.querySelectorAll('pre[class*="language-"]');

                    codeBlocks.forEach(function(block) {
                        // Only add line-numbers if it isn't present
                        if (!block.className.includes('line-numbers')) {
                            block.className += ' line-numbers';
                            console.log('Added line-numbers to:', block.className);
                        }
                    });

                    // Return modified content
                    evt.content = tempDiv.innerHTML;
                }
            });
        });
    }
});

This code is responsible for changing any occurence of class="language- to class="language- line-numbers while keeping the selected language.

Secondly we make Bludit loading this scriptfile by adding a line in bl-kernel/admin/themes/booty/index.php. Open it and search for the closing head-element (I mean </head>). The included plugins should be right above that.

Here, add the following: <script src="<?php echo DOMAIN_ADMIN_THEME.'js/custom-linenumbers.js' ?>"></script>

So your result will look like this:

[...]
        ?>

        <!-- Plugins -->
        <?php Theme::plugins('adminHead') ?>
        <script src="<?php echo DOMAIN_ADMIN_THEME.'js/custom-linenumbers.js' ?>"></script>

</head>
[...]

That's it.

You still need to update your bl-plugins/prism/css/prism.css and bl-plugins/prism/js/prism.js files with a version downloaded from https://prismjs.com/. Make sure the CSS includes the line-numbers plugin, it's not selected per-default. Also, to make Bludit use that also enable the Prism-Plugin in Bludit beforehand if you don't have it already. Sadly the Bludit Prism-Plugin doesn't include the line-numbers plugin, so we need to go this route.

Verify it works

Log into Bludit and hit F12 to display the Browser console. You should see the message Loaded: custom-linenumbers.js in there.

Create a new post, add a codeblock and select any language. On saving the codeblock you should see the message Added line-numbers to: ...

If you want to get rid of the message comment them out, by change the lines into //console.log...

Comments

WHATWG, Firefox and bad ports

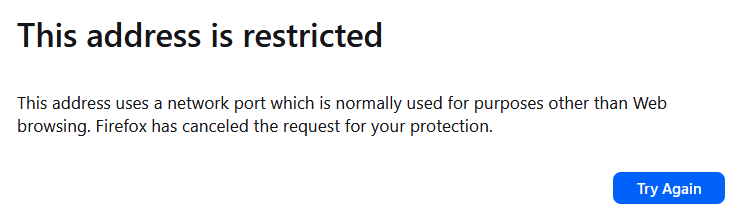
When I setup my Termix instance I used port 6666/tcp. However on my first visit I wasn't greeted with a Termix login page, rather a Firefox message appeared. One I had never encountered before.

Huh? What? I use all kinds of strange ports in my home network and never got that error message.
I was kind of annoyed that there was no button labeled "I know the risk, take me there anyway".

However a quick search showed the solution.

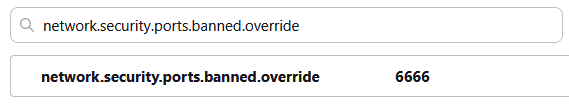
  1. Open about:config
  2. Enter: network.security.ports.banned.override
    • The key doesn't exist per-default
  3. Create it as type "String"
  4. Add the port number
    • If multiple ports are needed specify them as a comma separated list: 6666,7777

This is how it looks in my case:

What ports are blocked? And why?

If we look at the source code, we see the list of ports that is blocked: https://searchfox.org/firefox-main/source/netwerk/base/nsIOService.cpp#122

In total just shy over 80 ports are blocked. And there seems to be no separation between UDP or TCP ports.

A bit more Firefox context is in their Knowledge Base: https://kb.mozillazine.org/Network.security.ports.banned

They get this port list from the "The Web Hypertext Application Technology Working Group (WHATWG)" who define a list of "bad ports" in this document: https://fetch.spec.whatwg.org/#port-blocking

Apparently "A port is a bad port if it is listed in the first column of the following table.", well you never stop learning. 😉

Comments

This blog is now officially not indexed on Google anymore - and I don't know why [Update]

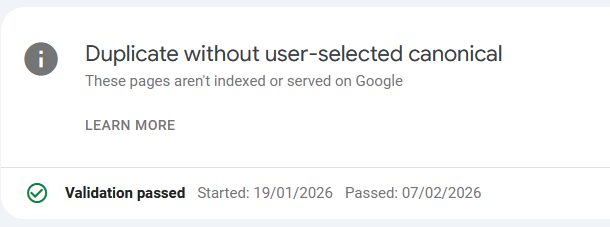
Update: Passed the validation, still not indexed

I just noticed that I passed the "Duplicate without user-select canonical" check a good week ago, after doing the modifications in Adding canonical links for category and tag pages in Bludit 3.16.2.

Still nothing changed regarding the indexing.

Update end.

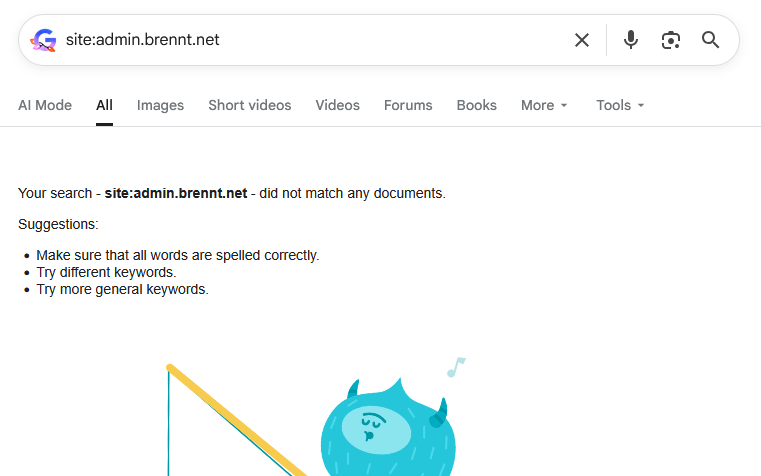
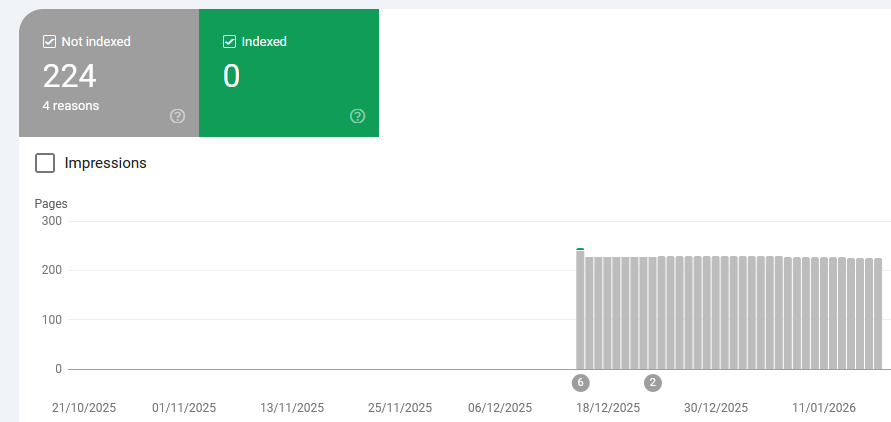
If you do a search in Google specifically for this blog, it will show up empty. Zero posts found, zero content shown. In the last weeks less and less content was shown until we reached point zero on December 28th, 2025.

And I have absolutely no clue about the reason. Only vague assumptions.

I do remember my site being definitely indexed and several results being shown. This was how I spotted lingering DNS entries from other peoples long-gone web projects still pointing to the IP of my server. Which I blogged about in "It's always DNS." in November 2024.

This lead me to implement a HTTP-Rewrite rule to redirect the requests for those domains to a simple txt-file asking the people in a nice way to remove those old DNS entries. This can still be found here: https://admin.brennt.net/please-delete.txt

However since December 19th 2025 no pages are indexed anymore.

HTTP-302, the first mistake?

And maybe here I made the first mistake which perhaps contributed to this whole situation. As according to the Apache documentation on the Redirect flag HTTP-302 "Found" is used as the default status code to be used. Not the HTTP-301 "Moved permanently" status code. Hence I signaled Google "Hey, the content only moved temporarily".

And this Apache configuration DOES send a HTTP-302:

# Rewrite for old, orphaned DNS records from other people..
RewriteEngine On
<If "%{HTTP_HOST} == 'berufungimzentrum.at'">
    RewriteRule "^(.*)$" "https://admin.brennt.net/please-delete.txt"
</If>

Anyone having some knowledge in SEO/SEM will tell you to avoid HTTP-302 in order to not be punished for "duplicate content". And yeah, I did know this too, once. Sometime, years ago. But I didn't care too much and had forgotten about this.

And my strategy to rewrite all URLs for the old, orphaned domains to this txt-file lead to a situation where the old domains were still seen as valid and the content indexed through them (my blog!) as valid content.

Then suddenly my domain appeared too, but the old domains were still working and all requests temporarily redirected to some other domain (admin.brennt.net - my blog..). Hence I assume that currently my domain is flagged for duplicate content or being some kind of "link-farm" and therefore not indexed.

And I have no clue if this situation will resolve itself automatically or when.

A slow but steady decline

Back to the beginning. Around mid of October 2025 I grew curious how my blog shows up in various search engines. And I was somewhat surprised. Only around 20 entries where shown for my blog. Why? I had no clue. While I could understand that the few posts, which garnered some interest and were shared on various platforms, were listed first, this didn't explain why only so few pages were shown.

I started digging.

The world of search engines - or: Who maintains an index of their own

The real treasure trove which defines what a search engine can show you in the results is its index. Only if a site is included in its index it is known to the search engine. Everything else is treated like it doesn't exist.

However not every search engine maintains its own index. https://seirdy.one/posts/2021/03/10/search-engines-with-own-indexes/ has a good list of search engines and if they are really autonomous in maintaining their own index or not. Based on this I did a few tests with search engines for this blog. I solely used the following search parameter: site:admin.brennt.net

Search Engine Result
Google No results
Bing Results found
DuckDuckGo Results found
Ecosia Results found if using Bing, no results with Google
Brave Results found
Yandex Results found

Every single search engine other than Google properly indexes my blog. Some have recent posts some are lagging behind a few weeks. This however is fine and solely depends on the crawler and index update cycles of the search engine operator.

My webserver logs also prove this to be true. Zero visitors with a referrer from Google, but a small and steady number from Bing, DuckDuckGo and others.

So why does only Google have problem with my site?

Can we get insights with the Google Search Console?

I went to the Google Search Console and verified admin.brennt.net as my domain. Now I was able to have a deep dive into what Google reported about my blog.

robots.txt

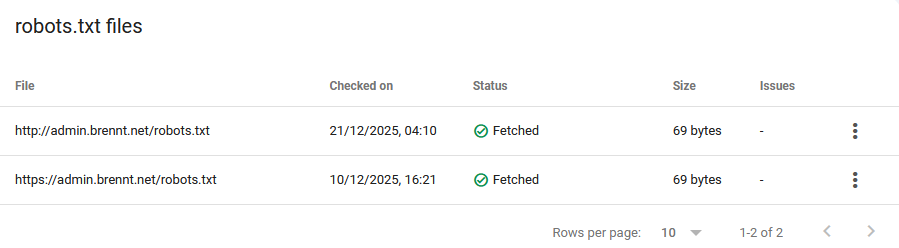
My first assumption was that the robots.txt was somehow awry but given how basic my robots.txt is I was dumbfounded on where it was wrong. "Maybe I missed some crucial technical development?" was the best guess I had. No, a quick search revealed that nothing has changed regarding the robots.txt and Google says my robots.txt is fine.

Just for the record, this is my robots.txt. As plain, boring and simple as it can be.
User-agent: *
Allow: /
Sitemap: https://admin.brennt.net/sitemap.xml

Inside the VirtualHost for my blog I use the following Rewrite to allow HTTP and HTTPS-Requests for the robots.txt to succeed. As normally all HTTP-Requests are redirected to HTTPS. The Search Console however complained about being an error present with the HTTP robots.txt..

RewriteEngine On
# Do not rewrite HTTP-Requests to robots.txt
<If "%{HTTP_HOST} == 'admin.brennt.net' && %{REQUEST_URI} != '/robots.txt'">
    RewriteRule "(.*)"      "https://%{HTTP_HOST}%{REQUEST_URI}" [R=301] [L]
</If>

But this is just house keeping. As that technical situation was already present when my blog was properly indexed. If at all, this should lead to my blog being ranked or indexed better, and not vanish..

Are security or other issues the problem?

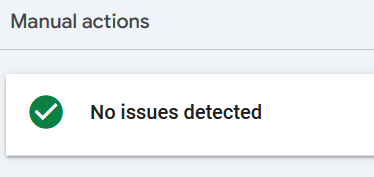
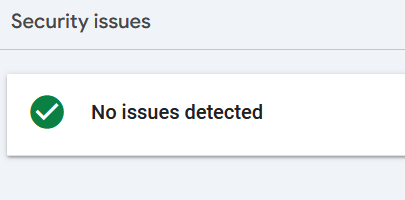
The search console has the "Security & Manual Actions" menu. Under it are these two mentioned reports about Security issues and issues requiring manual interaction.

Again, no. Everything is fine.

Is my sitemap or RSS-Feed to blame?

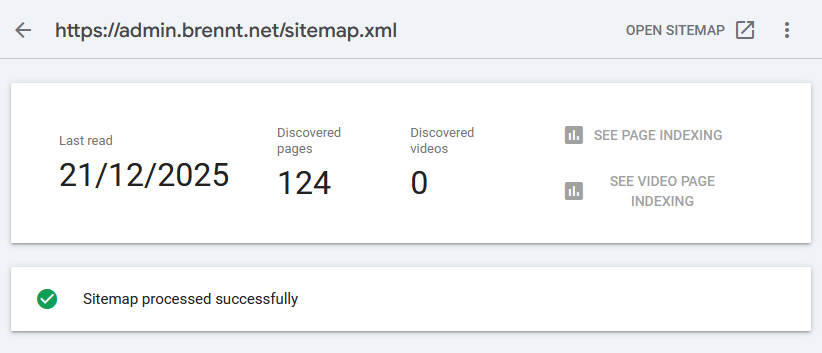
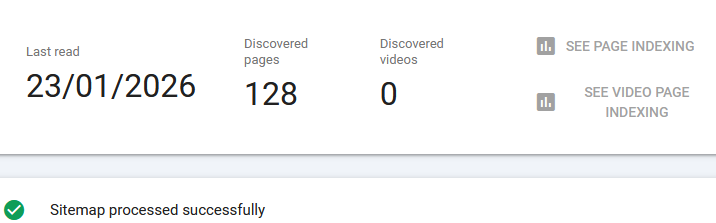
I read some people who claim that Google accidentally read their RSS-Feed as Sitemap. And that excluding a link to their RSS-Feed in the sitemap.xml did the trick. While a good point, my RSS-Feed https://admin.brennt.net/rss.xml isn't listed in my sitemap. Uploading the Sitemap in the Search Console also showed no problems. Not in December 2025 and not in January 2026.

It even successfully picked up the newly creating articles.

However even that doesn't guarantee that Google will index your site. It's just one minor technical detail checked for validity.

"Crawled - currently not indexed" the bane of Google

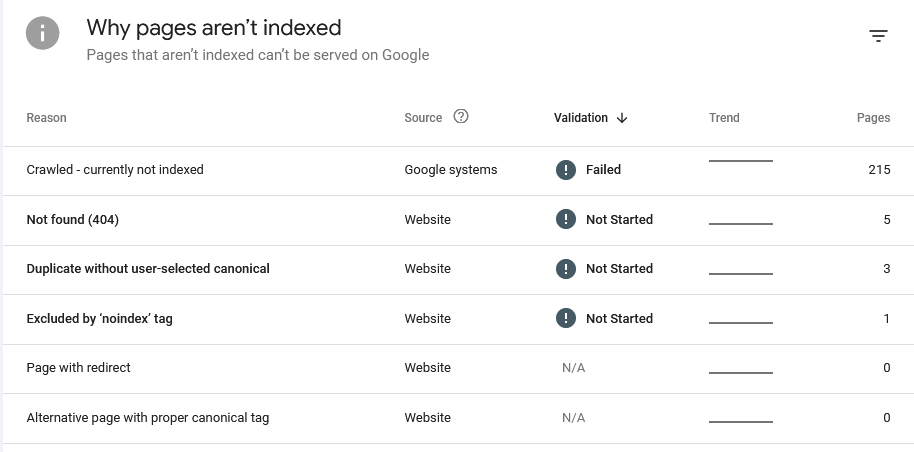
Even the "Why pages aren't indexed" report didn't provide much insight. Yes, some links deliver a 404. Perfectly fine, I deleted some tags, hence those links now end in a 404. And the admin login page is marked with noindex. Also as it should be.

The "Duplicate without user-selected canoncial" took me a while to understand, but it boils down to this: Bludit has categories and tags. If you click on such a category-/tag-link you will be redirected to an automatically generated page showing all posts in that category/with that tag. However, the Bludit canonical-plugin currently doesn't generate these links for category or tag views. Hence I fixed it myself.

Depending on how I label my content some of these automatically generated pages can look the same i.e. a page for category A can show the exact same posts as the page for tag B. What a user then has to do is define a canonical link in the HTML source code to make it possible to properly distinguish these sites and tell Google that, yes, the same content is available under different URLs and this is fine (this is especially a problem with bigger sites being online for many years).

But none of these properly explain why my site isn't indexed anymore. As most importantly: All these issues were already present when my blog was indexed. Google explains the various reasons on its "Page indexing report" help page.

There we learn that "Crawled - currently not indexed" means:

The page was crawled by Google but not indexed. It may or may not be indexed in the future; no need to resubmit this URL for crawling.
Source: https://support.google.com/webmasters/answer/7440203#crawled

And that was the moment I hit a wall. Google is crawling my blog. Nothing technical prevents Google from doing so. The overall structure is fine, no security issues or other issues (like phishing or other fraudulent activities) are done under this domain.

So why isn't Google showing my blog!? Especially since all other search engines don't seem to have an issue with my site.

Requesting validation

It also didn't help that Google itself had technical issues which prevented the page indexing report from being up-to-date. Instead I had to work with old data at that time.

I submitted my Sitemap and hoped that this will fix the issue. Alas it didn't. While the sitemap was retrieved and processed near instantly and showed a Success-Status along with the info that it discovered 124 pages... None of them were added.

I requested a re-validation and the search console told me it can take a while (they stated around 2 weeks, but mine took more like 3-4 weeks).

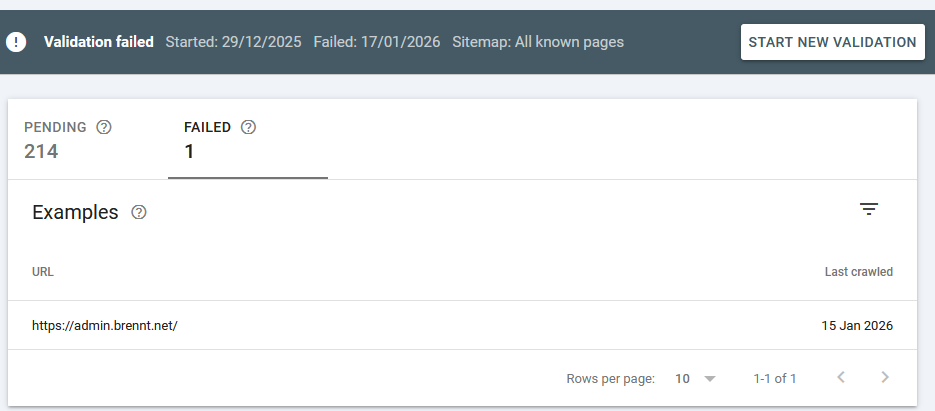
Fast-forward to January 17th 2026 and the result was in: "Validation failed"

What this means is explained here: https://support.google.com/webmasters/answer/7440203#validation

The reason is not really explained, but I took with me the following sentence:

You should prioritize fixing issues that are in validation state "failed" or "not started" and source "Website".

So I went to fix the "Duplicate without user-selected canonical" problem, as all others (404, noindex) are either no problems or are there intentionally. This shouldn't be a problem however, as Google itself writes the following regarding validation:

It might not always make sense to fix and validate a specific issue on your website: for example, URLs blocked by robots.txt are probably intentionally blocked. Use your judgment when deciding whether to address a given issue.

With that being fixed, I requested another validation in mid-January 2026. And now I have to wait another 2-8 weeks. *sigh*

A sudden realization

And then it hit me. I vaguely remember that Google scores pages based on links from other sites. Following the mantra: "If it's good quality content, people will link to it naturally." My blog isn't big. I don't have that many backlinks. And I don't to SEO/SEM.

But my blog was available under at least one domain which had a bit of backlink traffic - traffic I can still see in my webserver logs today!

Remember how my blog's content was first also reachable under this domain? Yep. My content was indexed under this domain. Then I changed the webserver config so that this isn't the case anymore. Now I send a proper HTTP-410 "Gone". With that... Did I nuke all the (borrowed) reputation my blog did possess?

If that should be the case (I have yet to dig into this topic..) the question will likely be: How does Google treat a site which backlinks vanished, or more technical, how to properly move content from one domain to another. And is there anything I can do afterwards to fix this, if I did it wrong.

Anything else?

If you are familiar with the topic and have an idea what I can check, feel free to comment. As currently I'm at my wits end.

Comments

Webinars & data gathering

Someone I follow on LinkedIn announced a webinar regarding OPNsense and a paid plugin. As I currently use OPNsense a little in my home lab, I was mildly interested. Unfortunately, the webinar was scheduled to take place during a customer meeting. When I asked about a recording of the webinar, I was told that:

"Yes, there will be a recording. The link will be send to all participants after the meeting. So just register and you are fine."

Cool, I thought.

Yeah but mandatory fields are:

  • Full name
  • Phone number
  • Mail address
  • Company
  • Position
  • Country
  • Postcode

I know that this is for gathering contacts, or 'leads' in sales terms. After all, it's a paid OPNsense plugin. I am also familiar with services such as "Frank geht ran" (Frank takes the call), which is operated by the data privacy NGO Digital Courage. They provide two numbers: One is a mobile number and the other is a landline number. If you call, a recorded message informs the caller that the person they are calling does not wish to receive any more telephone calls.

But... I just couldn't be bothered. I could have provided a disposable email address with a fake company name and a "Frank geht ran" phone number. Or I could have saved myself all the trouble and ignored it. Which is what I did.

Comments

Disabling the accuweather feature in Firefox

Mozila incooperated yet another feature nobody asked for. And of course it's turned on per-default. Screw you Mozilla!

Some people seem to have this feature for weeks as it's gradually rolled out, I got it today. Now whenever I typed a city name in the adressbar I would get a small window from accuweather showing me the current temperature. And from what I read online even the location data is shared!? What the heck Mozilla?

Naturally my immediate action was to disable this bullshit.

Open about:config and then change the following values:

browser.urlbar.weather.featureGate = false
browser.newtabpage.activity-stream.feeds.weatherfeed = false
browser.newtabpage.activity-stream.showWeather = false
browser.newtabpage.activity-stream.system.showWeatherOptIn = false
browser.newtabpage.activity-stream.weather.locationSearchEnabled = false

if you want to see all parameters associated with this feature, search for: browser.newtabpage.activity-stream.*weather

Sources:

Comments