Feuerfest

Just the private blog of a Linux sysadmin

yt-dlp error "No video formats found" and how I learned about DASH and that my yt-dlp filter could be improved

I participated in an only workshop at the weekend and the organisers kindly provided the recording as an unlisted YouTube video. As I wanted to watch the video again at a later time I used my MeTube installation to download the YouTube video. Or rather: Tried to.

As the download would fail. MeTube would say no available formats could be found. The video however played nicely on YouTube!?

The setup

I use a self-hosted web frontend for yt-dlp in Docker called MeTube, configured through the YTDL_OPTIONS environment variable. My config looked like this:

YTDL_OPTIONS={ "cookiefile":"/downloads/cookies/cookies.txt", "format-sort": "res:1080", "format": "best[language^=de]/best[language^=en]/b", "merge_output_format": "mp4" }

The idea behind this filter was:

  1. Limit video to 1080p in quality (not higher)
  2. Use the best available version with German audio
  3. Else use the best available version with English audio
  4. Use whatever is available as fallback

Step 1: Debugging

Naturally my first move was to check what kind of formats are offered for this video in order to verify the error message.

user@host:~$ yt-dlp -F "https://www.youtube.com/watch?v=VIDEO_ID"

For clarity I removed some lines and columns to make it more easier to read:

ID  EXT   RESOLUTION │ VCODEC          ACODEC      MORE INFO
─────────────────────────────────────────────────────────────────────
139 m4a   audio only │ audio only      mp4a.40.5   low, m4a_dash
140 m4a   audio only │ audio only      mp4a.40.2   medium, m4a_dash
251 webm  audio only │ audio only      opus        medium, webm_dash
134 mp4   640x360    │ avc1.4D401E     video only  360p, mp4_dash
136 mp4   1280x720   │ avc1.64001F     video only  720p, mp4_dash
137 mp4   1920x1080  │ avc1.640028     video only  1080p, mp4_dash
398 mp4   1280x720   │ av01.0.05M.08   video only  720p, mp4_dash
399 mp4   1920x1080  │ av01.0.08M.08   video only  1080p, mp4_dash

Notice something? Every single format is either audio only or video only. There is not one single format which contains both. Remember that for later.

Step 2: Why my filter found nothing

In yt-dlp's format selection best (or b) means: the best single file which contains video AND audio. And there are none. So all three alternatives of my filter (best[language^=de], best[language^=en] and b) ran into the void. Hence the error: "No video formats found!". The formats exist, my filter just didn't select any of them.

Nowadays YouTube serves high-quality video and audio as separate streams (DASH, see my separate article). yt-dlp downloads both and merges them with ffmpeg (provided it is installed and yt-dlp can find it) afterwards. For this you need to select video and audio separately and join them with a +:

bv* = best video (the * also allows formats which already have audio)
ba = best audio
bv*+ba = download both and merge them

Step 3: The corrected filter?

"format": "bv*+ba[language^=de]/bv*+ba[language^=en]/bv*+ba/b"

Read from left to right: Best video plus German audio. If there is no German audio then best video plus English audio. If that doesn't work either, best video plus whatever audio there is. And only if everything fails, the old b as a last resort.

I tested this on the command line first and it worked.

However.. It failed for another video. The video had English and German audio, according to the filter I should have gotten the video with the German audio track, but I didn't.

And here is where DASH becomes relevant: ba works for non-combined formats ONLY, meaning: ba only matches results with "audio only" under RESOLUTION (when using yt-dlp -F) Which is the case when DASH is used. On older videos however this might not be the case and you have only combined formats available. ba simply ignores these and hence my /b fallback matched and gave me the default audio track.

For combined formats we have to use best or b.

Step 4: The new filter 

Long story short, I ended up with the following filter which takes care of both, combined and non-combined, formats along with audio-only content:

'YTDL_OPTIONS={ "format-sort": "res:1080", "format": "bv*+ba[language^=de]/bv*+ba[language^=en]/b[language^=de]/b[language^=en]/bv*+ba/b/ba[language^=de]/ba[language^=en]/ba", "merge_output_format":"mp4" }'

  • format: alternatives separated by /, tried left to right, first match wins
    1. bv*+ba[language^=de]: best "video only" + best German "audio only"
    2. bv*+ba[language^=en]: best "video only" + best English "audio only"
    3. b[language^=de]: best combined format with German audio
    4. b[language^=en]: best combined format with English audio
    5. bv*+ba: best "video only" + best "audio only", any language
    6. b: best combined video+audio format
    7. ba[language^=de]: best German audio-only (for content without video)
    8. ba[language^=en]: best English audio-only (for content without video)
    9. ba: best audio-only, any language

This should be sufficient for the future (I hope! 😂) as I also took care to handle audio-only content.
Comments

What is DASH (Dynamic Adaptive Streaming over HTTP) and why did it broke my yt-dlp filter?

When you run yt-dlp -F on a YouTube video you will see lots of entries ending in mp4_dash, webm_dash or m4a_dash. I thought at first that this is a new format, so I started searching. As my current filter would complain: "No video formats found!"

The short version

DASH stands for Dynamic Adaptive Streaming over HTTP, also known as MPEG-DASH. It is an international standard (first described in ISO/IEC 23009-1) for streaming video and audio over plain HTTP. The same protocol your browser uses to load any webpage.

The core idea: Don't send one big file. Cut the media into many small segments, offer them in several qualities, and let the player decide which quality it wants to fetch next. And reading this, I finally understood a bit more how some things related to streaming work (yeah, all that audio/video stuff is not my bright side).

The problem DASH solves

Before adaptive streaming there were basically two options to watch a video on the web:

  1. Download the whole file (progressive download)
    • Simple, but you can't react if your connection gets slower. The video just stutters and buffers.
  2. Special streaming servers and protocols like RTMP (remember Flash?)
    • They worked, but needed dedicated server software (remember RealServer or RealPlayer?), were a pain with firewalls and didn't play well with caches and CDNs from what I read.

DASH takes a different approach: A video is just a bunch of static files on a normal web server. No special server logic required. Any HTTP server or CDN can deliver it. That's a big reason why it became so popular.

How it works

1. Encoding: many qualities, small segments

The provider encodes the video several times, in different resolutions and bitrates (144p, 360p, 720p, 1080p, ...). Each of these versions is called a Representation. Every representation is then cut into segments, usually a few seconds long.

Video and audio are separate representations. (Keep this in mind if you want to setup yt-dlp!) Audio can also exist in several bitrates, codecs and languages.

2. The XML-manifest tying everthing together

A small XML file, the Media Presentation Description (MPD), describes what is available. Which representations exist, which codecs, which bitrates and where to find the segments.

A heavily simplified, non-working example - as there are many attributes, etc. missing, is below:
Note: I use YouTube IDs here to make it easier to understand how yt-dlp, DASH/MPD and YouTube play together:

<MPD type="static" mediaPresentationDuration="PT10M">
  <Period>
    <AdaptationSet mimeType="video/mp4">
      <Representation id="137" codecs="avc1.640028" width="1920" height="1080" bandwidth="3500000"/>
      <Representation id="136" codecs="avc1.64001F" width="1280" height="720"  bandwidth="2000000"/>
      <Representation id="134" codecs="avc1.4D401E" width="640"  height="360"  bandwidth="700000"/>
    </AdaptationSet>
    <AdaptationSet mimeType="audio/mp4" lang="de">
      <Representation id="140" codecs="mp4a.40.2" bandwidth="129000"/>
    </AdaptationSet>
  </Period>
</MPD>

The AdaptationSet groups interchangeable versions of the same thing (e.g. "the video in different resolutions" or "the German audio track in different bitrates"). The player picks one representation out of each set.

Real world examples can be found here, but I can't say if they are up-to-date or working:

3. The player does the thinking

The player downloads the MPD and then:

  1. Starts with a low or medium quality, so playback begins quickly.
  2. Measures how fast the segments arrive (and how full its buffer is).
  3. Switches to a higher or lower representation for the next segment, depending on the result.

That is the "adaptive" in the name. It's also why a YouTube video gets blurry for a moment when your WLAN is acting up, instead of stopping to buffer. The server isn't even involved in this decision. It just hands out files.

This provided a nice "Ahhh!"-moment for me, as now I understood the technical details of how streaming services achieve this.

How it plays out is basically this:

Server (plain HTTP):        Player:
video_1080p/seg001.m4s ---> fast connection -> fetch 1080p
video_1080p/seg002.m4s ---> fetch segment 2
video_360p/seg003.m4s  ---> connection drops -> switch to 360p
video_720p/seg004.m4s  ---> recovered -> raise to 720p
audio_de/seg001.m4s    ---> audio is fetched independently

Why video and audio are separate

This is the part that matters for yt-dlp. Because video and audio are independent representations, a provider doesn't need to store every combination of resolution and language as an own file. Imagine a video with 8 resolutions, 3 codecs and 5 languages. Without separation that would be 120 files (8*3*5). With DASH it is 24 video representations (8*3) plus 5 audio ones. And the player combines them on the fly.

The downside for us as downloaders: There is often no single file containing both video and audio in high quality. That's why a plain best format selector in yt-dlp can come up empty on YouTube, as I happened to experience today. You have to select video and audio separately and merge them (which needs ffmpeg), but luckily yt-dlp does this for us too if ffmpeg (see: https://github.com/yt-dlp/yt-dlp#strongly-recommended) can be found in your systems environment variables (like PATH).

To download a video with that filter, use:

user@host:~$ yt-dlp -f "bv*+ba" "URL"

bv* is the best video, ba the best audio and the + tells yt-dlp to download both and merge them.

DASH in the yt-dlp format list

In the yt-dlp -F output you recognise DASH streams by the _dash suffix in the MORE INFO column:
Note: For clarity I removed several columns (like FPS, CH, FILESIZE, etc.) in this output.

user@host:~$ yt-dlp -F https://www.youtube.com/watch?v=ID
[youtube] Extracting URL: https://www.youtube.com/watch?v=ID
[youtube] ID: Downloading webpage
[youtube] ID: Downloading visionos player API JSON
[youtube] ID: Downloading m3u8 information
[info] Available formats for ID:
ID  EXT   RESOLUTION │ VCODEC        ACODED      MORE INFO
─────────────────────────────────────────────────────────────────────
137 mp4   1920x1080  │ avc1.640028   video only  1080p, mp4_dash
140 m4a   audio only │ audio only    mp4a.40.2   medium, m4a_dash
251 webm  audio only │ audio only    opus        medium, webm_dash

The container (mp4, webm, m4a) is independent of DASH. DASH only describes how the media is delivered, not what is inside. It is codec-agnostic: H.264, VP9, AV1, AAC, Opus, all of that works.

And now you know why your player never asks you which of the 20 formats it should play and why the video quality automatically fixes it itself after network/bandwidth issues. 😅

Comments

First spam comment! Woohoo!

Today I received the first spam comment in this blog. Of course it sounded like it was written by an AI..

Took quite a while when you consider that this blog is running since June 20th, 2023. 😆😅

But since the old internet is pretty much dead, my blog is still de-listed from the Google index the traffic broke down pretty much completely. Hence I receive nearly no comments at all and therefore comments are still on moderation and auto-notification via Telegram bot so the spam comment wasn't publicly readable at all. 😏

Comments

Is Microsoft sabotaging the VLC project on purpose?

Yesterday I learned something which left in quite a bit of shock.

I have noticed that it takes a considerable amount of time (like 30 seconds) for the video to start playing when I watch movies stored on my NAS from my Windows 10 gaming PC. And stupid me was really searching for any error in my network, my NAS, etc. As VLC worked fine for years. Never ever would I have suspected that Microsoft's corporate policy is likely to blame.

Huh? What?

Why VLC suddenly takes 30 seconds to start (and no it is NOT VLC's fault)

VLC isn't one big monolithic .exe file. It's built almost entirely out of plugins for codecs, demuxers, I/O modules all loaded dynamically at runtime. After all one reason for the popularity of VLC is the vast support for any imaginable media file format. Parsing every single plugin binary on every startup would be slow, so VLC keeps an index of them in a file called plugins.dat. Read the index, load what you need, done in milliseconds.

That's the theory. In practice it means plugins.dat is a single point of failure. If something gets between VLC and that file VLC can't read its index. And what could get into the way? Well.. Maybe.. Microsoft Defender flagging it, scanning it, locking it during a background check. That kind of things. No index means VLC falls back to manually scanning the entire plugin directory from scratch. That's your 30 second hang, right there, every time Defender decides to interfere again. Great! Anti-Viruses make us so secure, right?

This also explains the classic pattern some people report: First launch of the day is agonizingly slow, then it's instant for the rest of the session. Once the cache scan clears and VLC gets its index back, it stays fine until Defender flags it again on some later background pass.

Why the story got messy and I suspect an evil actor to be at play

VideoLAN pinned this on a Defender bug introduced in a Windows 11 update, and pushed vlc-cache-gen.exe (regenerates the plugin cache) as the fix. Fair enough. Except their own bug tracker tells a slightly different story. At least one reporter said regenerating plugins.dat did nothing, but dropping in a known-good cache file did fix it, even though a plugins.dat already existed on disk. That's not "missing cache," that's "Defender interfering with an existing, valid cache." Different failure mode, same symptom.

So both camps in the bug tracker were right for their own case. Some machines just need a cache rebuild. Others have Defender actively poisoning a perfectly fine cache. Either way, Defender is the common denominator.

I however find it suspecting that immediately some people in the Internet used this to start defamatory campaigns against OpenSource software. Claiming "A bug like this should never exist" or "Why VLC needs a plugin-cache at all". Which both are pretty stupid arguments in my view. Anti-Virus scanners are known to be one of the main sources for pain in regards to software stability. The whole AV industry is just a big mess. I've seen enough bad AV-Kernel modules on Linux machines. And if you search for "Anti-Virus scanner bricks Windows PCs" plenty of results will show up. So yeah..

What made me realise something other might be going on is this: One person even claimed he now uses the Microsoft Media Player. Wow! That piece of garbage which can't play many commonly used formats? And lacks so many features VLC has?

Bold claim!

Let's just say I notice this pattern regularly towards OpenSource software. If you can't attack the quality of the software itself.. Go create an artificial fault and use that as base argument for your critic.. Yeah..

And it's not that Microsoft hasn't shown this nasty pattern of force-pushing their services and software onto their users. Even against their will! Even when the users explicitly disabled - or even removed - a feature Microsoft just deliberately enables it again at the next opportunity..

The actual fix I use

Regenerating the cache or reinstalling VLC treats the symptom. It WILL come back the next time Defender scans the folder again. If you want it to actually stay fixed, exclude the VLC folder from Defender scanning:

Windows Security → Virus & threat protection → Manage settings → Exclusions → Add an exclusion → Folder: C:\Program Files\VideoLAN\VLC

Or via PowerShell, if you're scripting this:

Add-MpPreference -ExclusionPath "C:\Program Files\VideoLAN\VLC"

Sadly I trust the VLC project more, than Microsoft fixing this bug...

Comments

Configuring Termux after a ROM-Update

Just a reminder for myself..

I recently updated the LineageOS on my mobile and hence had to revert to the official Stock ROM first. Due to this I, of course, also had to reinstall all apps.

These are the steps I do to configure Termux (Github, F-Droid) on my mobile.

  1. After install pkg update followed by pkg upgrade
  2. Allow Termux to access the SD-Card storage, so it can read my private SSH-keys: termux-setup-storage
    • Then either provide that path to the keyfile in the .ssh/config like this: /storage/emulated/0/<folder on SD-Card>
    • Or copy the private keyfile to ~/.ssh/, then you are able to revoke the storage permissions again.
  3. Install correct SSH package and agent: pkg install ssh-agent openssh
    • Create ~/.ssh/config and test it
  4. Test SSH-Connections to various servers
  5. Install various tools
    • pkg install dnsutils openssl-tool nmap traceroute
Comments

trustscope.app corrects the Google reviews situation in Germany at least a little bit

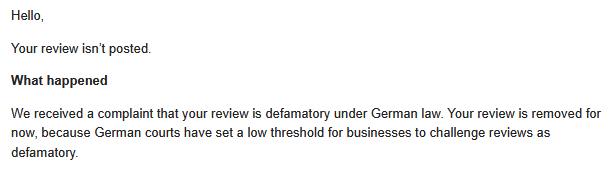
If you ever reviewed a business on Google in Germany you may be familiar with this mail:

In Germany it is pretty easy to get rid of bad, but honest, reviews. The business owner just needs to claim the review is defamatory and Google has to remove it. Shifting the burden of prove towards the reviewer. Often this includes lengthy discussions with lawyers as many business use the services of specialised law-firms.

Which also creates a scenario of financial ruin for people as legal battles can be costly and mistakes are easily made..

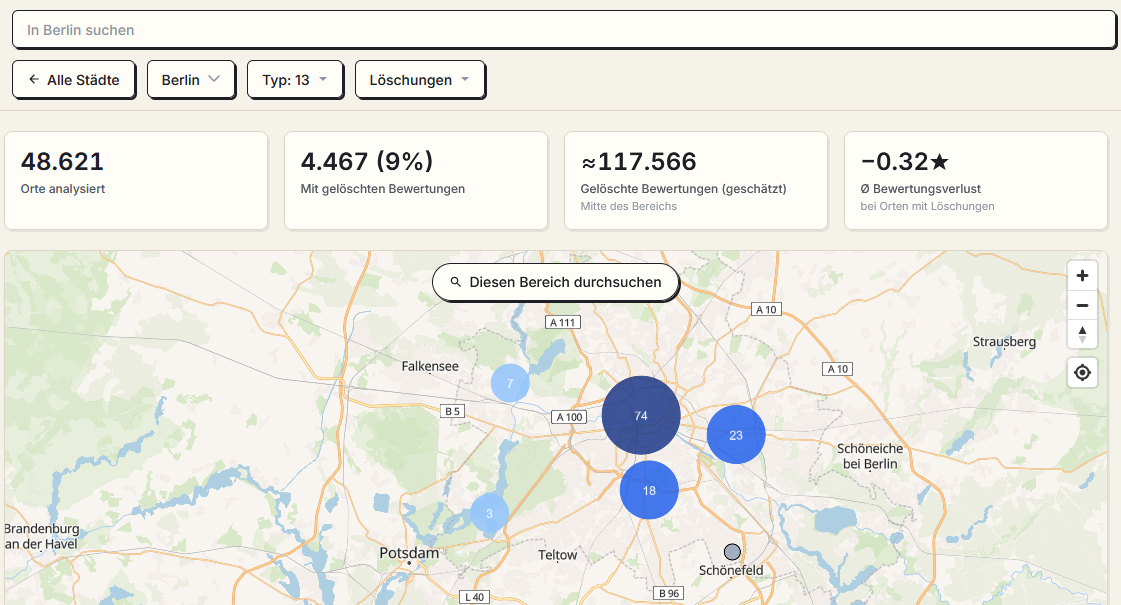
As I wrote recently Google now started to display the approximately number of deleted reviews due to defamation. Creating a crucial metric which enables Google Map users to reach an informed decision.

And it didn't take long for someone to scrape that data and take it into account when calculating the "real" score of a business. Of course these numbers are just an approximation, and we have no data on rightfully vs. wrongfully deleted reviews. After all, it is still a nice project: https://trustscope.app/

Comments